Hi! I am Haoxuan Xu (Harrison, 徐浩轩).
I am a first-year PhD student at the Hong Kong University of Science and Technology (HKUST), advised by Prof. Yuan Liu in the Intelligent Graphics Lab. I received my MPhil in Robotics and AI from HKUST (Guangzhou), advised by Prof. Haoang Li. Previously, I earned my B.Eng. from the School of Information Science and Engineering at Shandong University (Chongxin College), advised by Prof. Yang Yang. My research focuses on embodied intelligence and computer vision, with an emphasis on perception, reasoning, and policy learning in dynamic real-world environments.
📰 News
- Two papers (first / co-first author) accepted to NeurIPS 2026.
- Started my PhD at HKUST, advised by Prof. Yuan Liu.
- One co-first-author paper accepted to IROS 2026.
- One paper accepted to ICML 2026.
- One paper accepted to ICRA 2026.
🎓 Education


💼 Experience


🚀 Research Interests
- Embodied Intelligence
- Computer Vision
My research interests lie in embodied intelligence and computer vision, especially perception, reasoning, and policy learning for agents operating in dynamic real-world environments.
If you are interested in any aspect of me, I am always open to discussions and collaborations. Feel free to reach out to me at haoxuan.xu [at] connect.ust.hk.
📝 Publications († denotes equal contribution)
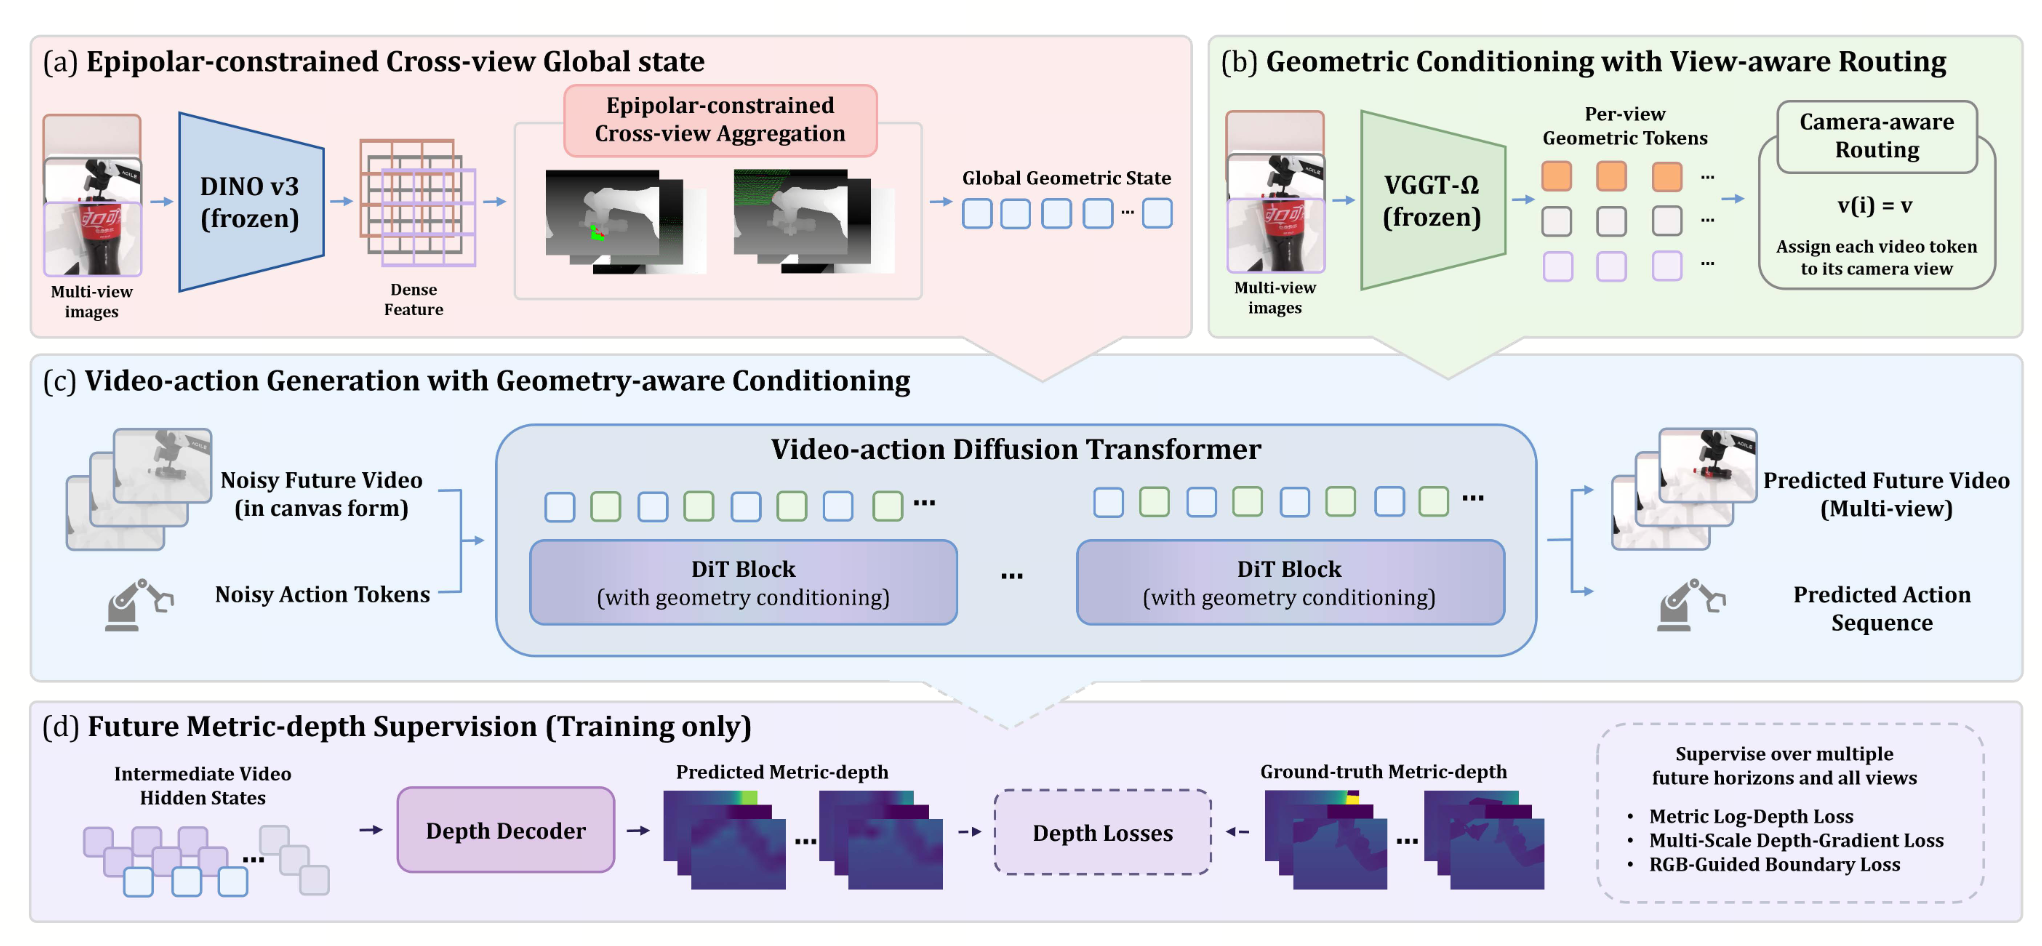
MVG-WAM: Multiple View Geometry-Aware World-Action Modeling for Robotic Manipulation
ArXiv Preprint · Project & Demos
Wenbo Chen†, Tianfu Li†, Haoxuan Xu†, et al.
- Integrates explicit multi-view geometry into world-action modeling for robust robotic manipulation.
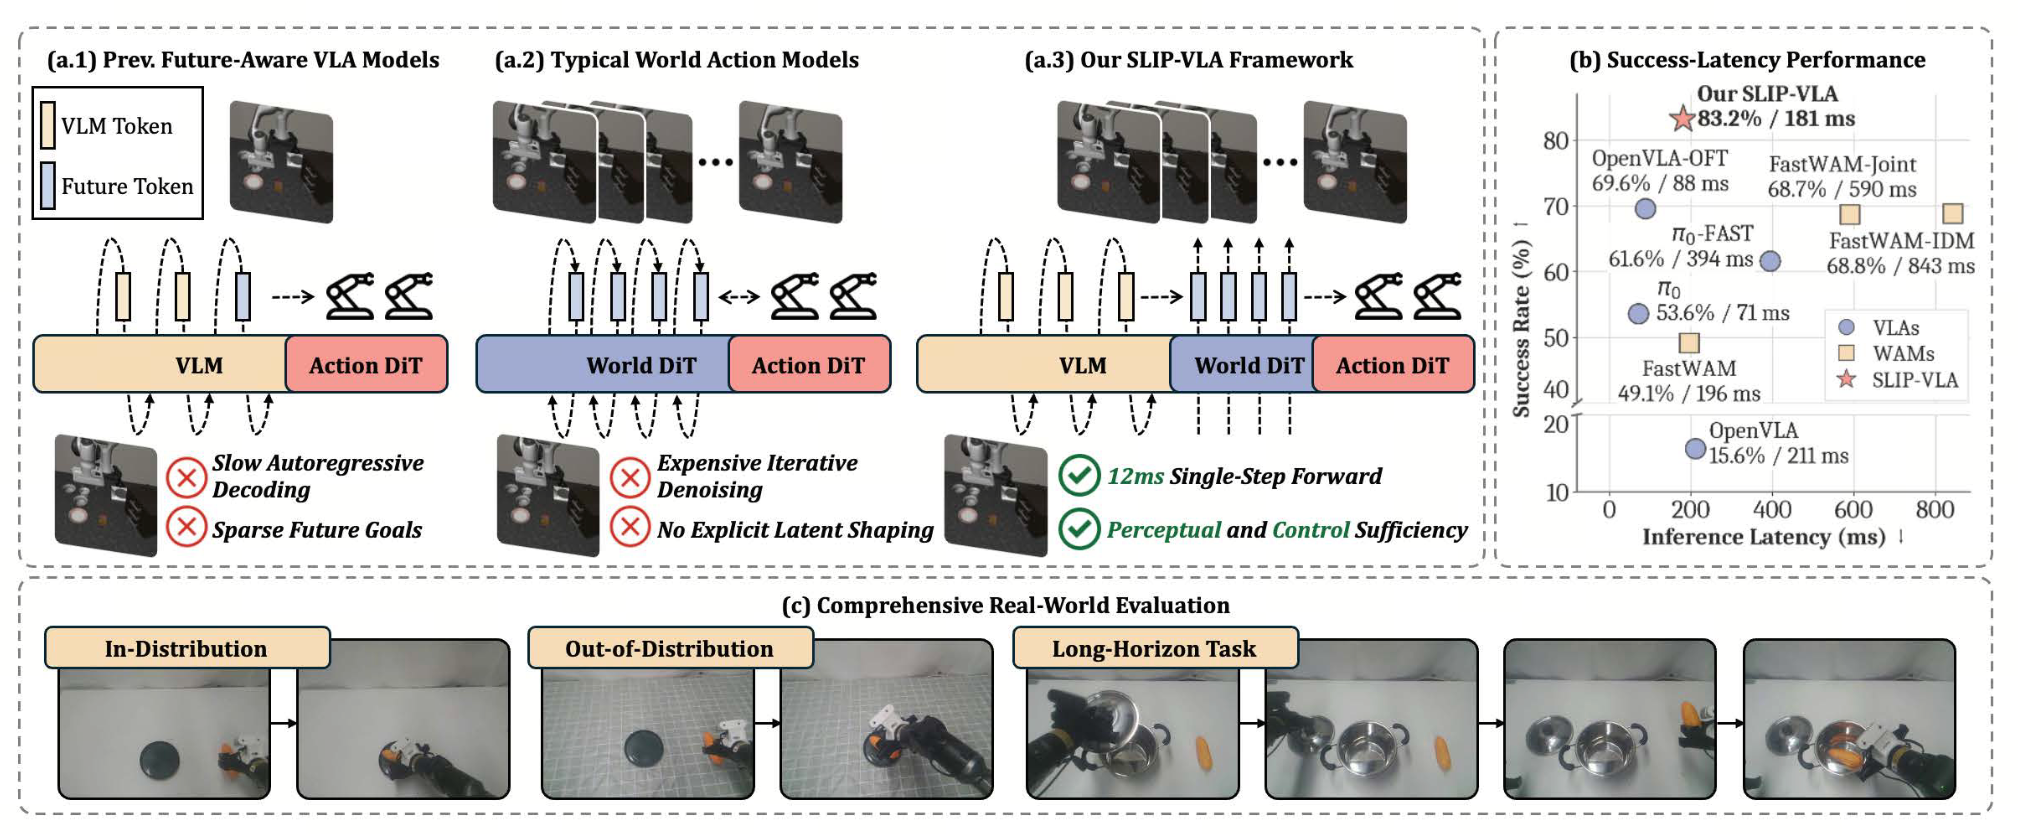
SLIP-VLA: Single-Step Latent Imagination for Policy Learning in Vision-Language-Action Models
ArXiv Preprint · Project & Demos
Tianfu Li†, Haoxuan Xu†, Wenbo Chen†, et al.
- Uses single-step future latent imagination to guide efficient, future-aware robot policy learning.

HCSG: Human-Centric Semantic-Geometric Reasoning for Vision-Language Navigation
ArXiv Preprint
Haoxuan Xu†, Tianfu Li†, Wenbo Chen, et al.
- Introduces a human-centric VLN framework that combines geometric human motion forecasting with semantic intention understanding for socially aware navigation.

Mask World Model: Predicting What Matters for Robust Robot Policy Learning
ICML 2026
Yunfan Lou, Xiaowei Chi, Xiaojie Zhang, …, Haoxuan Xu, et al.
- Learns predictive world models over semantic masks rather than raw pixels, improving robot policy robustness to visual distractions and distribution shifts.
GGD-SLAM: Monocular 3DGS SLAM Powered by Generalizable Motion Model for Dynamic Environments
ICRA 2026
Yi Liu, Haoxuan Xu, Hongbo Duan, Keyu Fan, Zhengyang Zhang, Peiyu Zhuang, Pengting Luo, Houde Liu
- Builds a monocular 3D Gaussian Splatting SLAM system for dynamic scenes by separating static mapping cues from dynamic distractors.

P3Nav: End-to-End Perception, Prediction and Planning for Vision-and-Language Navigation
ArXiv Preprint
Tianfu Li†, Wenbo Chen†, Haoxuan Xu†, Xinhu Zheng, Haoang Li
- Unified perception, prediction, and planning in a single VLN network, using intermediate modules to sharpen scene understanding and boost navigation accuracy.

ArXiv Preprint
Haoxuan Xu, Tianfu Li, Wenbo Chen, Yi Liu, Xingxing Zuo, Yaoxian Song, Haoang Li
- Constructs multimodal event knowledge from real-world indoor tour videos and injects it into VLN agents for long-horizon reasoning.

IRPO: Boosting Image Restoration via Post-training GRPO
ArXiv Preprint
Haoxuan Xu†, Yi Liu†, Tianfu Li, et al.
- Adapts GRPO-based post-training to image restoration with data-oriented sampling and reward-oriented optimization for stronger in-domain and OOD restoration.

Cross-domain Car Detection Model with Integrated Convolutional Block Attention Mechanism
Image and Vision Computing (JCR Q1, IF:4.7, CCF-C)
Haoxuan Xu†, Songnung Lai†, Yang Yang
- Proposed a complete cross-domain detection framework with an integrated CBAM architecture and GIOU loss optimization.

International Journal of Disaster Risk Science (JCR Q1 (IF: 5.0))
Mengfan Shen, Haoxuan Xu, Hongbing Liu and Ziqiang Han
- Applied topic modeling and sentiment analysis to Weibo posts, identifying key themes and public emotions during international disaster response.

Multimodal Sentiment Analysis: A Survey
Displays (JCR Q1 (IF: 4.3))
Songning Lai, Xifeng Hu, Haoxuan Xu, Zhaoxia Ren and Zhi Liu
- Provides a comprehensive overview of multimodal sentiment analysis, covering its history, datasets, advanced models, and future prospects.

MG-KG: Unsupervised video anomaly detection based on motion guidance and knowledge graph
Image and Vision Computing (JCR Q1, IF:4.7, CCF-C)
Qiyue Sun, Yang Yang, Haoxuan Xu, Zezhou Li, Yunxia Liu and Hongjun Wang
- Addresses spatio-temporal linkage and interpretability in VAD by unifying motion-guided prediction with knowledge-graph retrieval.
🔭 Projects

Research and Development of Embodied AI-based Multi-terrain Service Robot
- Used ConceptGraph for open-vocabulary scene mapping and CLIP/GPT4 for object retrieval.
- Implemented optimized A* and KD-Tree for path planning.
- Deployed on Songling chassis for sim-to-real transition.
🎖 Honors and Awards
- Postgraduate Studentship (PGS) Award, HKUST(GZ)
- First Prize, National College Student Mathematical Modeling Competition (Shandong Province)
- Second Prize, 14th National College Student Mathematics Competition
- Outstanding Graduate, Shandong University
🤝 Service
Reviewer: ICLR, ICRA, AAAI, and IEEE Robotics and Automation Letters (RA-L).